What we made
A vertical vlog of everyday life in China. Nobody went to China, and nothing was filmed.
What matters here is that the cut count is one.
0.00 ~ 30.07   Main film   1 generated clip — one prompt, one piece
30.07 ~ 39.00   Outro       still image + narration
────────────────────────────────────────────
                39.00 seconds
The Hong Kong noir piece before this one was 15 cuts generated separately and joined. This time a 30-second piece came out in a single pass. Scene changes, dialogue, expressions and background sound were all inside one prompt.
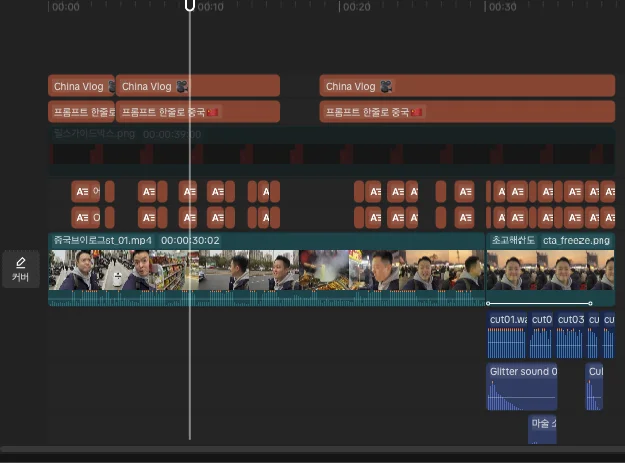
The figures were read directly from the CapCut project file.
How we made it
1. Prompt design   Claude        the full 30 seconds locked in writing as 5 beats
2. Generation      Seedance 2.5  1080x1920 · 30 seconds · generated once
3. Finishing       CapCut        captions · banner · outro
Stage 1 — Design the whole 30 seconds at once
To get it in one pass, the entire video has to be inside the prompt. So the 30 seconds were split into five beats, and for each beat we wrote down what is seen and what is said.
00:00-00:05   Hook         the reason to stop scrolling
00:05-00:12   Beat 2       a change of place or an interaction
00:12-00:20   The turn     where expectation and reality split
00:20-00:26   Climax       eating, touching, experiencing
00:26-00:30   Wrap-up      lowering the camera, a conclusion
The dialogue goes into the prompt too. Specify the tone and the length, or the lines come out awkward.
A reusable template
We turned it into a fill-in-the-blanks template so the same structure works for another country or another topic. Only the bracketed parts change.
Vlog prompt template — just fill in the blanks
Preserve the exact face, identity, skin tone, body proportions, facial
features, hairstyle, and outfit of the character throughout the entire
video. [gender/pronoun] wears [top]. [add bottoms/outerwear if any].
No appearance changes or identity drift.

Duration: [30] seconds
Aspect Ratio: 9:16 vertical, 1080x1920

Create an authentic [year] smartphone [genre: travel vlog / day-in-
the-life / food vlog] showing [one sentence on what to show].
The concept is: "[one-line logline — the reason to watch to the end]."
Avoid [cliches to avoid — e.g. tourist landmarks, staged shots].
Focus on [3-4 subjects to focus on].

VERTICAL FRAMING: Shot entirely in portrait orientation as if held in
one hand. Keep [pronoun] face and all key action within the middle third
of the vertical frame — the top and bottom edges will be covered by
graphics. Compose for vertical motion (walking forward, tilting up and
down) rather than wide horizontal pans.

00:00-00:05
[Hook. The reason to stop scrolling. Place + an unexpected discovery]
[pronoun] says naturally in Korean:
"[line 1 — a reflexive aside, under 10 characters]"

00:05-00:12
[Beat 2. A change of place or an interaction]
[pronoun] says in Korean:
"[line 2]"
[extra action], then reacts:
"[line 3]"

00:12-00:20
[Beat 3. The turn — where expectation and reality split]
[pronoun] says in Korean:
"[line 4 — what was expected]"
Brief pause, then:
"[line 5 — what was actually surprising]"

00:20-00:26
[Beat 4. Sensory climax — eating, touching, experiencing]
[pronoun] says in Korean:
"[line 6 — a short exclamation]"

00:26-00:30
[Beat 5. Wrap-up. Walking, lowering the camera]
[pronoun] looks into the camera and says in Korean:
"[line 7 — raise the question]"
[pronoun] turns the camera toward [subject]:
"[line 8 — the speaker's own conclusion]"
[pronoun] smiles and keeps walking as the phone lowers naturally.

VISUAL STYLE: Raw smartphone footage, natural handheld shake, autofocus
shifts, imperfect framing, realistic motion blur and exposure changes.
No cinematic lighting, beauty filters, stabilization, color grading,
subtitles or watermark.

AUDIO: Authentic smartphone microphone audio. The main character speaks
Korean clearly and casually, close to the phone mic. All background
voices and announcements are in [local language]. [4-5 ambient sounds] fill the
background at realistic volume, never louder than [pronoun] voice.

REALISM: Make everything look genuinely filmed by a traveler, not a
commercial or CGI video. Maintain consistent character appearance
throughout.
The prompt we actually used
The template above, filled in. The video above is the result of feeding in exactly these words. The character’s lines are in Korean on purpose; the video is a Korean traveler’s vlog.
Full China vlog prompt
Preserve the exact face, identity, skin tone, body proportions, facial
features, hairstyle, and outfit of the character throughout the entire
video. He wears a grey hoodie under a dark navy padded winter jacket.
No appearance changes or identity drift.

Duration: 30 seconds
Aspect Ratio: 9:16 vertical, 1080x1920

Create an authentic 2026 smartphone travel vlog showing a surprising
side of everyday China. The concept is: "The future is normal here."
Avoid tourist landmarks. Focus on ordinary streets, technology, local
food, and spontaneous reactions.

VERTICAL FRAMING: Shot entirely in portrait orientation as if held in
one hand. Keep his face and all key action within the middle third of
the vertical frame — the top and bottom edges will be covered by
graphics. Compose for vertical motion (walking forward, tilting up and
down) rather than wide horizontal pans.

00:00-00:05
Selfie footage while walking through an ordinary Chinese residential
neighborhood on an overcast winter afternoon. He notices an autonomous
delivery robot rolling along the sidewalk and turns the camera toward
it. People around him barely react.

He says naturally in Korean:
"어? 저거 진짜 배달하는 거예요?"

He laughs as the robot continues past him.

00:05-00:10
He enters a modern convenience store. Realistic shelves, drinks,
snacks, digital payment, everyday shoppers. He picks up an unfamiliar
local snack and looks at the camera.

He says in Korean:
"이게 뭔지 모르겠는데 일단 집었고"

He pays by scanning with his phone, then reacts:
"결제가 너무 쉬운데요?"

00:10-00:16
Outside, electric cars and scooters move almost silently past him. He
films them briefly, then turns the camera back to himself.

He says in Korean:
"미래 도시 같은 거 상상했거든요"

Brief pause, then:
"근데 그냥 평범한 길이 더 놀라워요"

00:16-00:23
He enters a lively local food street as evening falls. Steaming stalls,
cooks preparing noodles and skewers, pedestrians eating, bicycles and
scooters, authentic evening street ambience. He orders a skewer, takes
a bite, and reacts genuinely.

He says in Korean:
"이건 진짜 맛있다"

00:23-00:30
Golden-hour-to-evening selfie while walking through the busy street.
Warm storefront lights and everyday city life fill the background.

He looks into the camera and says in Korean:
"다들 유명한 중국만 보여주잖아요"

He turns the camera toward the street:
"근데 저는 이쪽이 더 신기했어요"

He smiles and keeps walking as the phone lowers naturally.

VISUAL STYLE: Raw smartphone footage, natural handheld shake, autofocus
shifts, imperfect framing, realistic motion blur and exposure changes.
No cinematic lighting, beauty filters, stabilization, color grading,
subtitles or watermark.

AUDIO: Authentic smartphone microphone audio. The main character speaks
Korean clearly and casually, close to the phone mic. All background
voices and shop announcements are in Chinese. Footsteps, scooters,
traffic, shop ambience, cooking sounds and natural crowd noise fill the
background at realistic volume, never louder than his voice.

REALISM: Make everything look genuinely filmed by a traveler, not a
commercial or CGI travel video. Maintain consistent character
appearance throughout.
One rule when you use it — attach one photo where your face is clearly visible. The prompt keeps referencing that face to hold the same person for all 30 seconds.
The sentences that actually made the difference
“No appearance changes or identity drift” — 30 seconds is long. Left alone, the face changes halfway through. Nail it down at the very top and the same person makes it to the end.
“Avoid tourist landmarks” — leave this out and you get the Great Wall. You have to say what not to do before you get an ordinary side street.
“The top and bottom edges will be covered by graphics” — vertical video gets captions and banners top and bottom. Tell the model in advance and it keeps the face and the key action in the middle.
“No cinematic lighting, beauty filters, stabilization” — you have to tell it not to make it pretty for it to look like it was really shot on a phone.
Stage 2 — Generate once
The prompt above went in as written and was generated once.
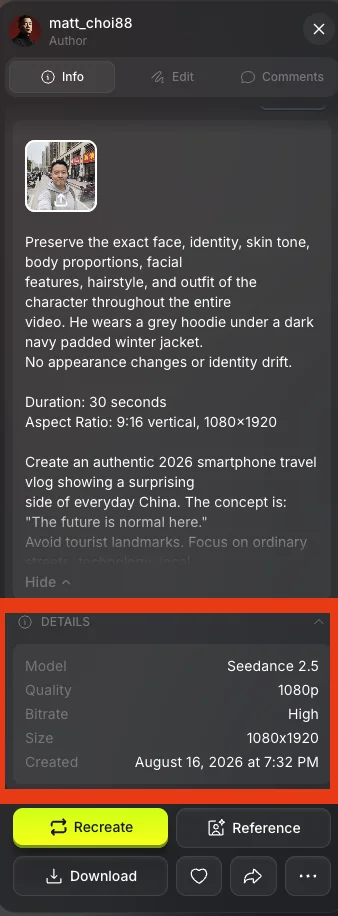
Model         Seedance 2.5
Quality       1080p · bitrate High
Size          1080 x 1920
Generated     August 16, 2026
Stage 3 — Finish in CapCut
The generated clip is 30.07 seconds. Captions and an outro were added to reach 39 seconds.
[Banner]     China Vlog 🎥 / a China vlog from a single prompt   two tiers · 3 spots
[Guide]      Reels guide box        laid over the full 39 s to check for clipped text
[Video]      1 generated clip (30.07 s) + outro still image (8.93 s)
[Captions]   Korean 25 · English 25   side by side
[Narration]  4 pieces               in the outro
[SFX]        sparkle, magic chime and one more, 3 in total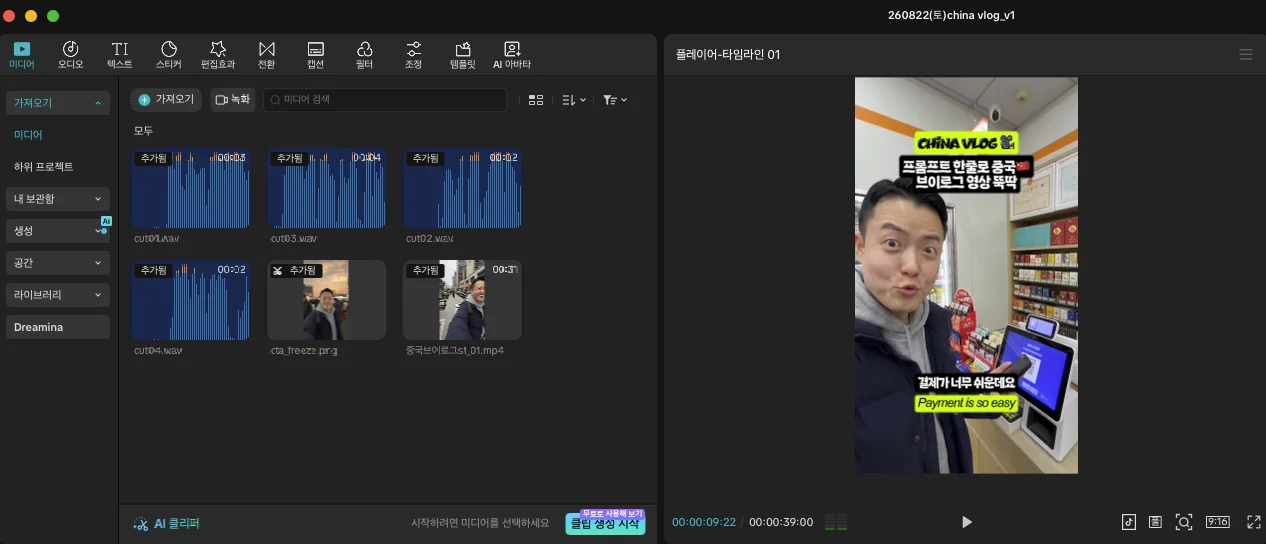
What we did here
No color grading. The prompt asked for “no color grading”, so grading it in the edit would break that intent. The opposite call from applying the Wong Kar-wai filter to the Hong Kong noir piece.
Laid captions in Korean and English together. 25 lines each.
Handled the outro with a still image. Instead of generating more video, one frame is frozen and the narration is laid over it. 8.93 seconds.
Comparing the two pieces
| Hong Kong noir | China vlog | |
|---|---|---|
| Generation | 15 cuts generated separately, then joined | 1 cut generated in one piece |
| Prompts | one per shot, 15 in total | one |
| Color grading | Wong Kar-wai filter | none (on purpose) |
| Goal | look like a film | look unstaged |
Neither is better. When you need to control the staging, split the cuts. When naturalness is the goal, generating it in one piece is better.
What we threw away
Getting 30 seconds in one pass doesn’t mean it succeeds in one pass. The face changed halfway, the lines didn’t match the mouth, or a tourist spot showed up. Those were filtered out before this one was chosen.
That is why the prompt is long. It is there to reduce the number of regenerations.